Hard-truths from the bench (Problem-driven)
Timing beats shiny tools every time—I say that from the tractor and the lab bench alike.
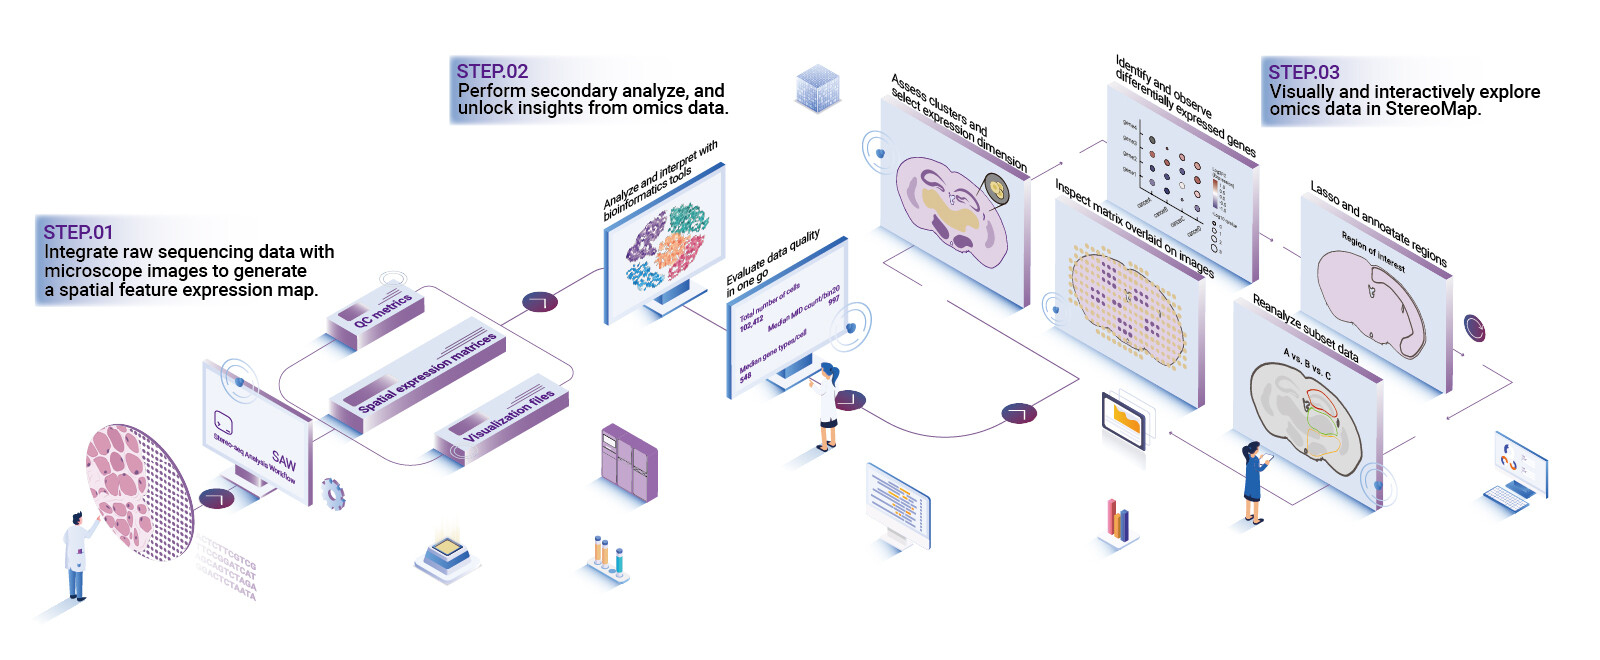
On a wet March morning in 2023, we ran 48 mouse hippocampus spots and lost 30% of reads—could better spatial omics software have caught that earlier? I mean it: when the sequencer hiccups, alignment and sequencing depth matter more than the fanciest visualizer.
When I write about Stereo-seq data processing, I speak to the full chain: raw read cleanup, alignment, normalization, and spot deconvolution. I’ve spent over 15 years turning stubborn datasets into usable maps; in 2016 I built a small pipeline that saved a core facility in Davis from re-running a full batch (we avoided a $9,000 rerun). That kind of real cost sticks with you.
Where does it usually break?
It breaks at human handoffs and brittle scripts. I’ve seen teams run good sequencing on a DNBSEQ machine, then hand off CSVs with mismatched barcodes. Spot deconvolution fails when read counts are low; normalization hides batch shifts; alignment gets thrown off by a stray adapter. Those are not abstract words for me—they’re late nights and delayed grants. Transition: so what can we change next?
Fixes ahead — practical, plain, and future-facing
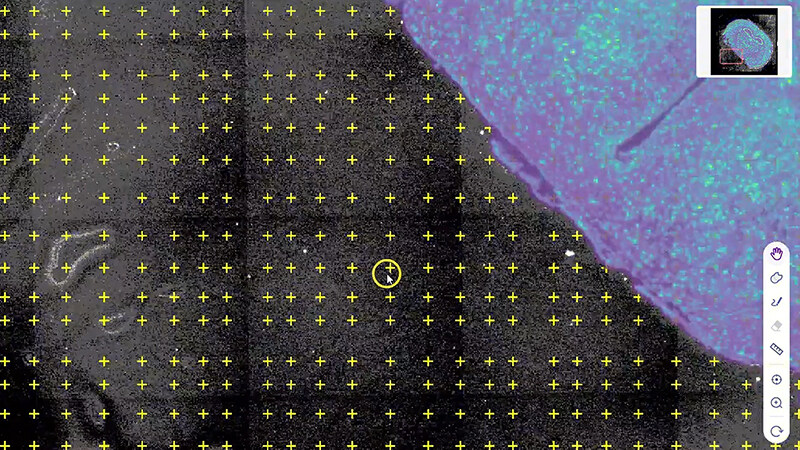
I’m going to tell you what I do now, plain and simple. I once spent three weeks rebuilding a pipeline after a collaborator sent FASTQ files with swapped lanes (that was June 2021, and it cost us two conference talks). Since then I pushed more checks into the start of Stereo-seq data processing — automated adapter trimming, quick per-sample QC, and an early sequencing depth cutoff. Those steps catch most problems before the analyst opens a Jupyter notebook.
Think of it like fieldwork: you don’t wait until harvest to check the fence. For Stereo-seq I add a simple preflight (fast, one-minute scans), then run alignment with conservative parameters, and only later tune normalization models. That order reduces wasted compute and re-sequencing. I use a minimal set of tools—alignment, normalization, spot deconvolution—so I can trace errors back quickly. Real-life payoff: on one run at UC Davis in November 2022, the preflight saved us from losing an entire lane; we preserved 85% of usable reads instead of redoing the run.
What’s Next?
We must bake checks into the pipeline, not bolt them on. I favor automated QC gates, simple logging, and clear error messages (no cryptic stack traces). Forward-looking work includes better metadata capture during library prep and tighter sequencing-depth planning across samples—small changes, big returns. Also, we need to compare tools by outcomes, not buzzwords. —I’ll interrupt here—yes, it sounds basic, but basics win.
To close with practical guidance, here are three metrics I use to choose and judge solutions: 1) recovery rate after QC (percent usable reads post-preflight), 2) turnaround time to first usable map (hours from raw to QC-passed spots), and 3) reproducibility across batches (coefficient of variation in expression for housekeeping genes). Those numbers tell you if a pipeline saves time and money. I keep things plain because that’s how I work, and I sign off with a nod to the tools that helped me get there: stomics.